# Deformable DETR
[Deformable DETR](https://huggingface.co/papers/2010.04159) 通过引入可变形注意力模块,对原始的 [DETR](./detr) 进行了改进。该机制选择性地关注参考点周围的一小组关键采样点。它提升了训练速度并提高了精度。
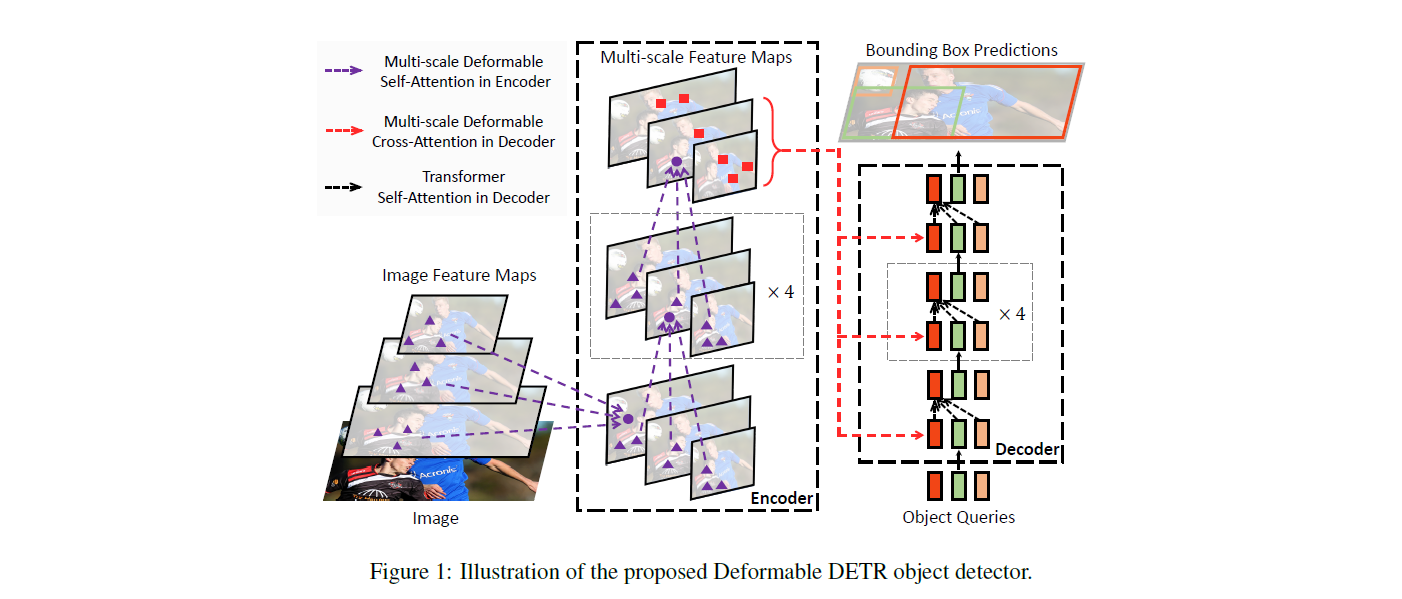 Deformable DETR 架构。摘自原始论文。
您可以在 [SenseTime](https://huggingface.co/SenseTime) 组织下找到所有可用的 Deformable DETR 检查点。
> [!TIP]
> 该模型由 [nielsr](https://huggingface.co/nielsr) 贡献。
>
> 点击右侧边栏中的 Deformable DETR 模型,以查看更多将 Deformable DETR 应用于不同目标检测和分割任务的示例。
以下示例演示了如何使用 [Pipeline](/docs/transformers/v5.23.0/zh/main_classes/pipelines#transformers.Pipeline) 和 [AutoModel](/docs/transformers/v5.23.0/zh/model_doc/auto#transformers.AutoModel) 类执行目标检测。
```python
from transformers import pipeline
pipeline = pipeline(
"object-detection",
model="SenseTime/deformable-detr",
device_map=0
)
pipeline("http://images.cocodataset.org/val2017/000000039769.jpg")
```
```python
import requests
import torch
from PIL import Image
from transformers import AutoImageProcessor, AutoModelForObjectDetection
url = "http://images.cocodataset.org/val2017/000000039769.jpg"
image = Image.open(requests.get(url, stream=True).raw)
image_processor = AutoImageProcessor.from_pretrained("SenseTime/deformable-detr")
model = AutoModelForObjectDetection.from_pretrained("SenseTime/deformable-detr", device_map="auto")
# prepare image for the model
inputs = image_processor(images=image, return_tensors="pt").to(model.device)
with torch.no_grad():
outputs = model(**inputs)
results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]]), threshold=0.3)
for result in results:
for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
score, label = score.item(), label_id.item()
box = [round(i, 2) for i in box.tolist()]
print(f"{model.config.id2label[label]}: {score:.2f} {box}")
```
## 资源
- 请参阅这组[notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Deformable-DETR),了解如何在自定义数据集上对[DeformableDetrForObjectDetection](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrForObjectDetection)进行推理和微调。
## DeformableDetrImageProcessor[[transformers.DeformableDetrImageProcessor]]
#### transformers.DeformableDetrImageProcessor[[transformers.DeformableDetrImageProcessor]]
```python
transformers.DeformableDetrImageProcessor(**kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/image_processing_deformable_detr.py#L271)
**参数:**
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`, *kwargs*, *可选*, 默认为 `True`) : 是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*,默认为 `{'shortest_edge' : 800, 'longest_edge': 1333}`):描述输入到模型的最大尺寸。
default_to_square (`bool`, *kwargs*, *可选*,默认为 `False`) : 当 size 为整数时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*,默认为 `2`) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*,默认为 `True`):是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*,默认为 `0.00392156862745098`) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`,*kwargs*,*可选*,默认为 `True`):是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*,默认为 `[0.485, 0.456, 0.406]`) : 用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*,默认为 `[0.229, 0.224, 0.225]`) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*,默认为 `True`) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
format (`str`, *kwargs*, *可选*,默认为 `AnnotationFormat.COCO_DETECTION`):注释的数据格式。取值为 "coco_detection" 或 "coco_panoptic" 之一。
do_convert_annotations (`bool`, *kwargs*, *可选*,默认为 `True`):控制是否将注释转换为 DEFORMABLE_DETR 模型所期望的格式。将边界框转换为 `(center_x, center_y, width, height)` 格式,且范围在 `[0, 1]` 内。可通过 `preprocess` 方法中的 `do_convert_annotations` 参数进行覆盖。
构建 DeformableDetrImageProcessor 图像处理器。
#### preprocess[[transformers.DeformableDetrImageProcessor.preprocess]]
```python
preprocess(images: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor']], annotations: dict[str, int | str | list[dict]] | list[dict[str, int | str | list[dict]]] | None = None, return_segmentation_masks: bool | None = None, masks_path: str | pathlib.Path | None = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/image_processing_deformable_detr.py#L526)
**参数:**
images (`Union[PIL.Image.Image, numpy.ndarray, torch.Tensor, list[PIL.Image.Image], list[numpy.ndarray], list[torch.Tensor]]`) : 要预处理的图像。期望输入单张或一批像素值在 0 到 255 之间的图像。如果传入的图像像素值在 0 到 1 之间,请设置 `do_rescale=False`。
annotations (`AnnotationType` 或 `list[AnnotationType]`,*可选*):根据应用于图像的填充进行转换的注释。
return_segmentation_masks (`bool`, *可选*, 默认为 `self.return_segmentation_masks`) : 是否返回分割掩码。
masks_path (`str` 或 `pathlib.Path`,*可选*):包含分割掩码的目录路径。
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`,*kwargs*,*可选*):是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`, *kwargs*, *可选*) : 当 size 为 int 时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*) : 是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
format (`str`, *kwargs*, *可选*,默认为 `AnnotationFormat.COCO_DETECTION`):注释的数据格式。取值为 "coco_detection" 或 "coco_panoptic" 之一。
do_convert_annotations (`bool`, *kwargs*, *可选*,默认为 `True`):控制是否将注释转换为 DEFORMABLE_DETR 模型所期望的格式。将边界框转换为 `(center_x, center_y, width, height)` 格式,且范围在 `[0, 1]` 内。可通过 `preprocess` 方法中的 `do_convert_annotations` 参数进行覆盖。
**返回:** `~image_processing_base.BatchFeature`
- **data** (`dict`) -- 由 __call__ 方法返回的列表/数组/张量字典(例如 'pixel_values')。
- **tensor_type** (`Union[None, str, TensorType]`,*可选*) -- 您可以在此处指定 tensor_type,以便在初始化时将 PyTorch/Numpy 张量中的整数列表进行转换。
#### post_process_object_detection[[transformers.DeformableDetrImageProcessor.post_process_object_detection]]
```python
post_process_object_detection(outputs, threshold: float = 0.5, target_sizes: transformers.utils.generic.TensorType | list[tuple] = None, top_k: int = 100)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/image_processing_deformable_detr.py#L667)
**参数:**
outputs (`DetrObjectDetectionOutput`):模型的原始输出。
threshold (`float`, *可选*) : 用于保留目标检测预测结果的分数阈值。
target_sizes (`torch.Tensor` 或 `list[tuple[int, int]]`,*可选*):形状为 `(batch_size, 2)` 的张量,或包含元组(`tuple[int, int]`)的列表,其中包含批次中每张图片的目标尺寸(高度、宽度)。如果设为 None,则不会调整预测结果的尺寸。
top_k (`int`,*可选*,默认为 100):在通过阈值过滤之前,仅保留前 k 个边界框。
**返回:** `list[Dict]`
一个字典列表,每个字典包含模型对批次中某张图像预测的分数、标签和边界框。
将 [DeformableDetrForObjectDetection](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrForObjectDetection) 的原始输出转换为 (top_left_x, top_left_y, bottom_right_x, bottom_right_y) 格式的最终边界框。仅支持 PyTorch。
## DeformableDetrImageProcessorPil[[transformers.DeformableDetrImageProcessorPil]]
#### transformers.DeformableDetrImageProcessorPil[[transformers.DeformableDetrImageProcessorPil]]
```python
transformers.DeformableDetrImageProcessorPil(**kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/image_processing_pil_deformable_detr.py#L263)
**参数:**
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`, *kwargs*, *可选*, 默认为 `True`) : 是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*,默认为 `{'shortest_edge' : 800, 'longest_edge': 1333}`):描述输入到模型的最大尺寸。
default_to_square (`bool`, *kwargs*, *可选*,默认为 `False`) : 当 size 为整数时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*,默认为 `2`) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*,默认为 `True`):是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*,默认为 `0.00392156862745098`) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`,*kwargs*,*可选*,默认为 `True`):是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*,默认为 `[0.485, 0.456, 0.406]`) : 用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*,默认为 `[0.229, 0.224, 0.225]`) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*,默认为 `True`) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
format (`str`, *kwargs*, *可选*,默认为 `AnnotationFormat.COCO_DETECTION`):注释的数据格式。取值为 "coco_detection" 或 "coco_panoptic" 之一。
do_convert_annotations (`bool`, *kwargs*, *可选*,默认为 `True`):控制是否将注释转换为 DEFORMABLE_DETR 模型所期望的格式。将边界框转换为 `(center_x, center_y, width, height)` 格式,且范围在 `[0, 1]` 内。可通过 `preprocess` 方法中的 `do_convert_annotations` 参数进行覆盖。
构建 DeformableDetrImageProcessor 图像处理器。
#### preprocess[[transformers.DeformableDetrImageProcessorPil.preprocess]]
```python
preprocess(images: typing.Union[ForwardRef('PIL.Image.Image'), numpy.ndarray, ForwardRef('torch.Tensor'), list['PIL.Image.Image'], list[numpy.ndarray], list['torch.Tensor']], annotations: dict[str, int | str | list[dict]] | list[dict[str, int | str | list[dict]]] | None = None, return_segmentation_masks: bool | None = None, masks_path: str | pathlib.Path | None = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/image_processing_pil_deformable_detr.py#L531)
**参数:**
images (`Union[PIL.Image.Image, numpy.ndarray, torch.Tensor, list[PIL.Image.Image], list[numpy.ndarray], list[torch.Tensor]]`) : 要预处理的图像。期望输入单张或一批像素值在 0 到 255 之间的图像。如果传入的图像像素值在 0 到 1 之间,请设置 `do_rescale=False`。
annotations (`AnnotationType` 或 `list[AnnotationType]`,*可选*):根据应用于图像的填充进行转换的注释。
return_segmentation_masks (`bool`, *可选*, 默认为 `self.return_segmentation_masks`) : 是否返回分割掩码。
masks_path (`str` 或 `pathlib.Path`,*可选*):包含分割掩码的目录路径。
do_convert_rgb (`bool`, *kwargs*, *可选*) : 是否将图像转换为 RGB。
do_resize (`bool`,*kwargs*,*可选*):是否调整图像大小。
size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*):描述模型的最大输入维度。
default_to_square (`bool`, *kwargs*, *可选*) : 当 size 为 int 时,是否在调整大小时默认使用正方形图像。
crop_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 应用 `center_crop` 后输出图像的尺寸。
resample (`Annotated[Union[int, PILImageResampling, NoneType], None]`, *kwargs*) : 如果调整图像大小,则使用的重采样滤波器。它可以是枚举 `PILImageResampling` 中的一个值。仅当 `do_resize` 设置为 `True` 时才会生效。
do_rescale (`bool`, *kwargs*, *可选*) : 是否对图像进行重新缩放。
rescale_factor (`float`, *kwargs*, *可选*) : 当 `do_rescale` 设置为 `True` 时,用于对图像进行缩放的缩放因子。
do_normalize (`bool`, *kwargs*, *可选*) : 是否对图像进行归一化。
image_mean (`Union[float, list[float], tuple[float, ...]]`,*kwargs*,*可选*):用于归一化的图像均值。仅当 `do_normalize` 设置为 `True` 时生效。
image_std (`Union[float, list[float], tuple[float, ...]]`, *kwargs*, *可选*) : 用于归一化的图像标准差。仅当 `do_normalize` 设置为 `True` 时生效。
do_pad (`bool`, *kwargs*, *可选*) : 是否对图像进行填充。填充操作会将图像填充至批次中的最大尺寸,或填充至每张图像的固定正方形尺寸。具体的填充策略取决于模型。
pad_size (`Annotated[int | list[int] | tuple[int, ...] | dict[str, int] | None, None]`, *kwargs*) : 用于将图像填充到的尺寸,格式为 `{"height": int, "width" int}`。该尺寸必须大于预处理中提供的任何图像尺寸。如果未提供 `pad_size`,图像将被填充到批次中最大的高度和宽度。仅在 `do_pad=True.` 时应用。
do_center_crop (`bool`, *kwargs*, *可选*) : 是否对图像进行居中裁剪。
data_format (`Union[str, ~image_utils.ChannelDimension]`,*kwargs*,*可选*):仅支持 `ChannelDimension.FIRST`。为兼容旧版处理器而添加。
input_data_format (`Union[str, ~image_utils.ChannelDimension]`, *kwargs*, *可选*) : 输入图像的通道维度格式。如果未设置,则从输入图像中推断通道维度格式。可以是以下之一: - `"channels_first"` 或 `ChannelDimension.FIRST`:图像为 (num_channels, height, width) 格式。 - `"channels_last"` 或 `ChannelDimension.LAST`:图像为 (height, width, num_channels) 格式。 - `"none"` 或 `ChannelDimension.NONE`:图像为 (height, width) 格式。
device (`Annotated[Union[str, torch.device, NoneType], None]`, *kwargs*):用于处理视频的设备。如果未设置,则从输入视频中推断设备。
return_tensors (`Annotated[str | ~utils.generic.TensorType | None, None]`, *kwargs*) : 如果设置为 `'pt'`,则返回堆叠的张量,否则返回张量列表。
disable_grouping (`bool`, *kwargs*, *可选*) : 是否禁用按尺寸对图像进行分组,从而逐个处理图像而非批量处理。如果为 None,则当图像位于 CPU 上时设置为 True,否则设置为 False。此选择基于经验观察,详见此处:https://github.com/huggingface/transformers/pull/38157
image_seq_length (`int`, *kwargs*, *可选*) : 输入中每张图片所使用的图像 token 数量。为向后兼容而添加,但在未来的模型中,应将其设置为处理器的属性。
format (`str`, *kwargs*, *可选*,默认为 `AnnotationFormat.COCO_DETECTION`):注释的数据格式。取值为 "coco_detection" 或 "coco_panoptic" 之一。
do_convert_annotations (`bool`, *kwargs*, *可选*,默认为 `True`):控制是否将注释转换为 DEFORMABLE_DETR 模型所期望的格式。将边界框转换为 `(center_x, center_y, width, height)` 格式,且范围在 `[0, 1]` 内。可通过 `preprocess` 方法中的 `do_convert_annotations` 参数进行覆盖。
**返回:** `~image_processing_base.BatchFeature`
- **data** (`dict`) -- 由 __call__ 方法返回的列表/数组/张量字典(例如 'pixel_values')。
- **tensor_type** (`Union[None, str, TensorType]`,*可选*) -- 您可以在此处指定 tensor_type,以便在初始化时将 PyTorch/Numpy 张量中的整数列表进行转换。
#### post_process_object_detection[[transformers.DeformableDetrImageProcessorPil.post_process_object_detection]]
```python
post_process_object_detection(outputs, threshold: float = 0.5, target_sizes: transformers.utils.generic.TensorType | list[tuple] = None, top_k: int = 100)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/image_processing_pil_deformable_detr.py#L676)
**参数:**
outputs (`DetrObjectDetectionOutput`):模型的原始输出。
threshold (`float`, *可选*) : 用于保留目标检测预测结果的分数阈值。
target_sizes (`torch.Tensor` 或 `list[tuple[int, int]]`,*可选*):形状为 `(batch_size, 2)` 的张量,或包含元组(`tuple[int, int]`)的列表,其中包含批次中每张图片的目标尺寸(高度、宽度)。如果设为 None,则不会调整预测结果的尺寸。
top_k (`int`,*可选*,默认为 100):在通过阈值过滤之前,仅保留前 k 个边界框。
**返回:** `list[Dict]`
一个字典列表,每个字典包含模型对批次中某张图像预测的分数、标签和边界框。
将 [DeformableDetrForObjectDetection](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrForObjectDetection) 的原始输出转换为 (top_left_x, top_left_y, bottom_right_x, bottom_right_y) 格式的最终边界框。仅支持 PyTorch。
## DeformableDetrConfig[[transformers.DeformableDetrConfig]]
#### transformers.DeformableDetrConfig[[transformers.DeformableDetrConfig]]
```python
transformers.DeformableDetrConfig(transformers_version: str | None = None, architectures: list[str] | None = None, output_hidden_states: bool | None = False, return_dict: bool | None = True, dtype: str | torch.dtype | None = None, chunk_size_feed_forward: int = 0, id2label: dict[int, str] | dict[str, str] | None = None, label2id: dict[str, int] | dict[str, str] | None = None, problem_type: Literal['regression', 'single_label_classification', 'multi_label_classification'] | None = None, is_encoder_decoder: bool = True, backbone_config: dict | transformers.configuration_utils.PreTrainedConfig | None = None, num_channels: int = 3, num_queries: int = 300, max_position_embeddings: int = 1024, encoder_layers: int = 6, encoder_ffn_dim: int = 1024, encoder_attention_heads: int = 8, decoder_layers: int = 6, decoder_ffn_dim: int = 1024, decoder_attention_heads: int = 8, encoder_layerdrop: float | int = 0.0, activation_function: str = 'relu', d_model: int = 256, dropout: float | int = 0.1, attention_dropout: float | int = 0.0, activation_dropout: float | int = 0.0, init_std: float = 0.02, init_xavier_std: float = 1.0, return_intermediate: bool = True, auxiliary_loss: bool = False, position_embedding_type: str = 'sine', dilation: bool = False, num_feature_levels: int = 4, encoder_n_points: int = 4, decoder_n_points: int = 4, two_stage: bool = False, two_stage_num_proposals: int = 300, with_box_refine: bool = False, class_cost: int = 1, bbox_cost: int = 5, giou_cost: int = 2, mask_loss_coefficient: int = 1, dice_loss_coefficient: int = 1, bbox_loss_coefficient: int = 5, giou_loss_coefficient: int = 2, eos_coefficient: float = 0.1, focal_alpha: float = 0.25, disable_custom_kernels: bool = False, tie_word_embeddings: bool = True)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/configuration_deformable_detr.py#L25)
**参数:**
is_encoder_decoder (`bool`,*可选*,默认为 `True`):模型是否用作编码器/解码器。
backbone_config (`Union[dict, ~configuration_utils.PreTrainedConfig]`,*可选*):骨干模型的配置。
num_channels (`int`,*可选*,默认为 `3`):输入通道数。
num_queries (`int`, *可选*,默认为 300):对象查询的数量,即检测槽位。这是 [DeformableDetrModel](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrModel) 在单张图像中可检测到的最大对象数量。如果 `two_stage` 设置为 `True`,则使用 `two_stage_num_proposals`。
max_position_embeddings (`int`,*可选*,默认为 `1024`):该模型可能使用的最大序列长度。
encoder_layers (`int`,*可选*,默认为 `6`):Transformer 编码器中的隐藏层数。如果未设置,将使用与 `num_layers` 相同的值。
encoder_ffn_dim (`int`, *可选*,默认为 `1024`):编码器中“中间”(通常称为前馈)层的维度。
encoder_attention_heads (`int`,*可选*,默认为 `8`):Transformer 编码器中每个注意力层的注意力头数量。
decoder_layers (`int`,*可选*,默认为 `6`):Transformer 解码器中的隐藏层数。如果未设置,将使用与 `num_layers` 相同的值。
decoder_ffn_dim (`int`,*可选*,默认为 `1024`):解码器中“中间”(通常称为前馈)层的维度。
decoder_attention_heads (`int`,*可选*,默认为 `8`):Transformer 解码器中每个注意力层的注意力头数量。
encoder_layerdrop (`Union[float, int]`,*可选*,默认为 `0.0`):编码器的 LayerDrop 概率。有关更多详细信息,请参阅 [LayerDrop 论文](see https://huggingface.co/papers/1909.11556)。
activation_function (`str`,*可选*,默认为 `relu`):解码器中的非线性激活函数(函数或字符串)。例如,`"gelu"`、`"relu"`、`"silu"` 等。
d_model (`int`,*可选*,默认为 `256`):编码器层和池化层的大小。
dropout (`Union[float, int]`,*可选*,默认为 `0.1`):所有 dropout 层的比率。
attention_dropout (`Union[float, int]`,*可选*,默认值为 `0.0`):注意力概率的 dropout 比率。
activation_dropout (`Union[float, int]`,*可选*,默认值为 `0.0`):全连接层内部激活值的 dropout 比率。
init_std (`float`,*可选*,默认值为 `0.02`):用于初始化所有权重矩阵的 truncated_normal_initializer 的标准差。
init_xavier_std (`float`, *可选*,默认为 `1.0`) : 用于交叉注意力权重 Xavier 初始化的缩放因子。
return_intermediate (`bool`, *可选*, 默认为 True) : 是否返回中间状态
auxiliary_loss (`bool`,*可选*,默认为 `False`):是否使用辅助解码损失(即每个解码器层的损失)。
position_embedding_type (`str`,*可选*,默认为 `"sine"`):用于叠加在图像特征之上的位置嵌入类型。取值为 `"sine"` 或 `"learned"` 之一。
dilation (`bool`,*可选*,默认为 `False`):是否将最后一个卷积块(DC5)中的 stride 替换为 dilation。仅在 `use_timm_backbone` = `True` 时支持。
num_feature_levels (`int`,*可选*,默认为 4):输入特征层级的数量。
encoder_n_points (`int`,*可选*,默认为 4):编码器中每个注意力头在每个特征层级中采样的键数量。
decoder_n_points (`int`,*可选*,默认为 4):解码器中每个注意力头在每个特征层级中采样的键数量。
two_stage (`bool`, *可选*, 默认为 `False`) : 是否应用两阶段可变形 DETR,其中区域建议也由 Deformable DETR 的变体生成,并进一步输入解码器以进行迭代边界框细化。
two_stage_num_proposals (`int`, *可选*,默认为 300):当 `two_stage` 设置为 `True` 时,要生成的区域提案数量。
with_box_refine (`bool`,*可选*,默认为 `False`):是否应用迭代边界框细化,其中每个解码器层会基于上一层的预测结果来细化边界框。
class_cost (`int`, *可选*,默认为 `1`):匈牙利匹配代价中分类误差的相对权重。
bbox_cost (`int`, *可选*,默认为 `5`):匈牙利匹配代价中 L1 边界框误差的相对权重。
giou_cost (`int`, *可选*,默认为 `2`):匈牙利匹配代价中广义 IoU 损失的相对权重。
mask_loss_coefficient (`int`, *可选*,默认为 `1`):全景分割损失中焦点损失的相对权重。
dice_loss_coefficient (`int`, *可选*, 默认为 `1`) : 全景分割损失中 dice loss 的相对权重。
bbox_loss_coefficient (`int`, *可选*,默认为 `5`):全景分割损失中 L1 边界框损失的相对权重。
giou_loss_coefficient (`int`, *可选*,默认为 `2`):全景分割损失中广义 IoU 损失的相对权重。
eos_coefficient (`float`, *可选*, 默认为 `0.1`) : 目标检测损失中“无目标”类别的相对分类权重。
focal_alpha (`float`, *可选*, 默认为 `0.25`) : 焦点损失中的 Alpha 参数。
disable_custom_kernels (`bool`,*可选*,默认为 `False`):禁用自定义 CUDA 和 CPU 内核。此选项对于 ONNX 导出是必需的,因为 PyTorch ONNX 导出不支持自定义内核。
tie_word_embeddings (`bool`,*可选*,默认为 `True`):是否根据模型的 `tied_weights_keys` 映射来绑定权重嵌入。
这是用于存储 DeformableDetrModel 配置的类。它根据指定的参数实例化 Deformable Detr 模型,并定义模型架构。使用默认值实例化配置将生成与 [SenseTime/deformable-detr](https://huggingface.co/SenseTime/deformable-detr) 类似的配置。
配置对象继承自 [PreTrainedConfig](/docs/transformers/v5.23.0/zh/main_classes/configuration#transformers.PreTrainedConfig),可用于控制模型输出。有关更多信息,请参阅 [PreTrainedConfig](/docs/transformers/v5.23.0/zh/main_classes/configuration#transformers.PreTrainedConfig) 的文档。
示例:
```python
>>> from transformers import DeformableDetrConfig, DeformableDetrModel
>>> # Initializing a Deformable DETR SenseTime/deformable-detr style configuration
>>> configuration = DeformableDetrConfig()
>>> # Initializing a model (with random weights) from the SenseTime/deformable-detr style configuration
>>> model = DeformableDetrModel(configuration)
>>> # Accessing the model configuration
>>> configuration = model.config
```
## DeformableDetrModel[[transformers.DeformableDetrModel]]
#### transformers.DeformableDetrModel[[transformers.DeformableDetrModel]]
```python
transformers.DeformableDetrModel(config: DeformableDetrConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/modeling_deformable_detr.py#L1145)
**参数:**
config ([DeformableDetrConfig](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrConfig)):模型配置类,包含模型的所有参数。通过配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
原始的 Deformable DETR 模型(由骨干网络和编码器-解码器 Transformer 组成),输出原始隐藏状态,顶部没有添加任何特定的头。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.DeformableDetrModel.forward]]
```python
forward(pixel_values: Tensor, pixel_mask: typing.Optional[torch.LongTensor] = None, decoder_attention_mask: typing.Optional[torch.Tensor] = None, encoder_outputs: typing.Optional[torch.Tensor] = None, inputs_embeds: typing.Optional[torch.Tensor] = None, decoder_inputs_embeds: typing.Optional[torch.Tensor] = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/modeling_deformable_detr.py#L1319)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`):与输入图像对应的张量。可以使用 `image_processor_class` 获取像素值。有关详细信息,请参阅 `image_processor_class.__call__`(`processor_class` 使用 `image_processor_class` 处理图像)。
pixel_mask (`torch.LongTensor`,形状为 `(batch_size, height, width)`,*可选*):用于避免对填充像素值执行注意力的掩码。掩码值取自 `[0, 1]`: - 1 表示真实像素(即 **未掩码**), - 0 表示填充像素(即 **已掩码**)。 [什么是注意力掩码?](../glossary#attention-mask)
decoder_attention_mask (`torch.Tensor`,形状为 `(batch_size, num_queries)`,*可选*):默认情况下不使用。可用于对对象查询进行掩码处理。
encoder_outputs (`torch.Tensor`, *可选*) : 由 (`last_hidden_state`, *可选*: `hidden_states`, *可选*: `attentions`) `last_hidden_state` 形状为 `(batch_size, sequence_length, hidden_size)`, *可选*) 组成的元组,是编码器最后一层输出的隐藏状态序列。用于解码器的交叉注意力。
inputs_embeds (`torch.Tensor`,形状为 `(batch_size, sequence_length, hidden_size)`,*可选*):可选地,除了传入展平的特征图(backbone + 投影层的输出)外,你还可以选择直接传入图像的展平表示。
decoder_inputs_embeds (`torch.Tensor`,形状为 `(batch_size, num_queries, hidden_size)`,*可选*):可选地,你可以选择直接传入嵌入表示,而不是用零张量来初始化查询。
**返回:** `DeformableDetrModelOutput` 或 `tuple(torch.Tensor)`
`DeformableDetrModelOutput` 或 `torch.Tensor` 元组(如果传入 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置(`None`)和输入。
[DeformableDetrModel](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrModel) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **init_reference_points**(形状为 `(batch_size, num_queries, 4)` 的 `torch.Tensor`)-- 通过 Transformer 解码器发送的初始参考点。
- **last_hidden_state**(形状为 `(batch_size, num_queries, hidden_size)` 的 `torch.Tensor`)-- 模型解码器最后一层输出的隐藏状态序列。
- **intermediate_hidden_states**(形状为 `(batch_size, config.decoder_layers, num_queries, hidden_size)` 的 `torch.Tensor`)-- 堆叠的中间隐藏状态(解码器每一层的输出)。
- **intermediate_reference_points**(形状为 `(batch_size, config.decoder_layers, num_queries, 4)` 的 `torch.Tensor`)-- 堆叠的中间参考点(解码器每一层的参考点)。
- **decoder_hidden_states** (`tuple[torch.Tensor]`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每个层输出的一个张量),形状为 `(batch_size, sequence_length, hidden_size)`。
解码器在每一层输出处的隐藏状态,以及初始嵌入输出。
- **decoder_attentions** (`tuple[torch.Tensor]`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
解码器在注意力 softmax 之后的注意力权重,用于在自注意力头中计算加权平均值。
- **cross_attentions** (`tuple[torch.Tensor]`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
解码器交叉注意力层在注意力 softmax 之后的注意力权重,用于在交叉注意力头中计算加权平均值。
- **encoder_last_hidden_state**(形状为 `(batch_size, sequence_length, hidden_size)` 的 `torch.Tensor`,*可选*)-- 模型编码器最后一层输出的隐藏状态序列。
- **encoder_hidden_states** (`tuple[torch.Tensor]`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每一层输出的一个张量),形状为 `(batch_size, sequence_length, hidden_size)`。
编码器在每一层输出处的隐藏状态,以及初始嵌入输出。
- **encoder_attentions**(`tuple[torch.Tensor]`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回)-- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
编码器在注意力 softmax 之后的注意力权重,用于在自注意力头中计算加权平均值。
- **enc_outputs_class** (`torch.Tensor`,形状为 `(batch_size, sequence_length, config.num_labels)`,*可选*,当 `config.with_box_refine=True` 且 `config.two_stage=True` 时返回) -- 预测的边界框分数,其中得分最高的 `config.two_stage_num_proposals` 个边界框在第一阶段被选为区域建议。边界框二分类(即前景和背景)的输出。
- **enc_outputs_coord_logits** (`torch.Tensor`,形状为 `(batch_size, sequence_length, 4)`,*可选*,当 `config.with_box_refine=True` 且 `config.two_stage=True` 时返回) -- 第一阶段中预测的边界框坐标的 logits。
示例:
```python
>>> from transformers import AutoImageProcessor, DeformableDetrModel
>>> from PIL import Image
>>> from huggingface_hub.utils import httpx
>>> from io import BytesIO
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> with httpx.stream("GET", url) as response:
... image = Image.open(BytesIO(response.read()))
>>> image_processor = AutoImageProcessor.from_pretrained("SenseTime/deformable-detr")
>>> model = DeformableDetrModel.from_pretrained("SenseTime/deformable-detr")
>>> inputs = image_processor(images=image, return_tensors="pt")
>>> outputs = model(**inputs)
>>> last_hidden_states = outputs.last_hidden_state
>>> list(last_hidden_states.shape)
[1, 300, 256]
```
## DeformableDetrForObjectDetection[[transformers.DeformableDetrForObjectDetection]]
#### transformers.DeformableDetrForObjectDetection[[transformers.DeformableDetrForObjectDetection]]
```python
transformers.DeformableDetrForObjectDetection(config: DeformableDetrConfig)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/modeling_deformable_detr.py#L1542)
**参数:**
config ([DeformableDetrConfig](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrConfig)):模型配置类,包含模型的所有参数。通过配置文件进行初始化时,不会加载与模型关联的权重,仅加载配置。请查看 [from_pretrained()](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel.from_pretrained) 方法以加载模型权重。
用于 COCO 检测等任务的 Deformable DETR 模型(由骨干网络和编码器-解码器 Transformer 组成),其顶部带有目标检测头。
该模型继承自 [PreTrainedModel](/docs/transformers/v5.23.0/zh/main_classes/model#transformers.PreTrainedModel)。请查阅父类文档,了解该库为所有模型实现的通用方法(例如下载或保存、调整输入嵌入大小、剪枝头等)。
该模型也是 PyTorch [torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) 的子类。请将其作为常规的 PyTorch Module 使用,有关通用用法和行为的所有事项,请参阅 PyTorch 文档。
#### forward[[transformers.DeformableDetrForObjectDetection.forward]]
```python
forward(pixel_values: Tensor, pixel_mask: typing.Optional[torch.LongTensor] = None, decoder_attention_mask: typing.Optional[torch.Tensor] = None, encoder_outputs: typing.Optional[torch.Tensor] = None, inputs_embeds: typing.Optional[torch.Tensor] = None, decoder_inputs_embeds: typing.Optional[torch.Tensor] = None, labels: list[dict] | None = None, **kwargs: *)
```
[来源](https://github.com/huggingface/transformers/blob/v5.23.0/src/transformers/models/deformable_detr/modeling_deformable_detr.py#L1580)
**参数:**
pixel_values (`torch.Tensor`,形状为 `(batch_size, num_channels, image_size, image_size)`):与输入图像对应的张量。可以使用 `image_processor_class` 获取像素值。有关详细信息,请参阅 `image_processor_class.__call__`(`processor_class` 使用 `image_processor_class` 处理图像)。
pixel_mask (`torch.LongTensor`,形状为 `(batch_size, height, width)`,*可选*):用于避免对填充像素值执行注意力的掩码。掩码值取自 `[0, 1]`: - 1 表示真实像素(即 **未掩码**), - 0 表示填充像素(即 **已掩码**)。 [什么是注意力掩码?](../glossary#attention-mask)
decoder_attention_mask (`torch.Tensor`,形状为 `(batch_size, num_queries)`,*可选*):默认情况下不使用。可用于对对象查询进行掩码处理。
encoder_outputs (`torch.Tensor`, *可选*) : 由 (`last_hidden_state`, *可选*: `hidden_states`, *可选*: `attentions`) `last_hidden_state` 形状为 `(batch_size, sequence_length, hidden_size)`, *可选*) 组成的元组,是编码器最后一层输出的隐藏状态序列。用于解码器的交叉注意力。
inputs_embeds (`torch.Tensor`,形状为 `(batch_size, sequence_length, hidden_size)`,*可选*):可选地,除了传入展平的特征图(backbone + 投影层的输出)外,你还可以选择直接传入图像的展平表示。
decoder_inputs_embeds (`torch.Tensor`,形状为 `(batch_size, num_queries, hidden_size)`,*可选*):可选地,你可以选择直接传入嵌入表示,而不是用零张量来初始化查询。
labels (`list[Dict]`,长度为 `(batch_size,)`,*可选*) : 用于计算二分匹配损失的标签。一个字典列表,每个字典至少包含以下 2 个键:'class_labels' 和 'boxes'(分别表示批次中某张图像的分类标签和边界框)。分类标签本身应是一个长度为 `(number of bounding boxes in the image,)` 的 `torch.LongTensor`,边界框应是一个形状为 `(number of bounding boxes in the image, 4)` 的 `torch.Tensor`。
**返回:** `DeformableDetrObjectDetectionOutput` 或 `tuple(torch.Tensor)`
`DeformableDetrObjectDetectionOutput` 或 `torch.Tensor` 元组(如果传入 `return_dict=False` 或 `config.return_dict=False`),其包含的元素取决于配置(`None`)和输入。
[DeformableDetrForObjectDetection](/docs/transformers/v5.23.0/zh/model_doc/deformable_detr#transformers.DeformableDetrForObjectDetection) 的 forward 方法重写了 `__call__` 特殊方法。
尽管前向传播的实现需要在此函数中定义,但之后应调用 `Module` 实例,而不是直接调用此函数,因为前者会负责执行预处理和后处理步骤,而后者会静默地忽略这些步骤。
- **loss** (`torch.Tensor`,形状为 `(1,)`,*可选*,在提供 `labels` 时返回)) -- 总损失,是类别预测的负对数似然(交叉熵)与边界框损失的线性组合。后者定义为 L1 损失与广义尺度不变 IoU 损失的线性组合。
- **loss_dict** (`Dict`, *可选*) -- 包含各项单独损失的字典。适用于日志记录。
- **logits**(形状为 `(batch_size, num_queries, num_classes + 1)` 的 `torch.Tensor`)-- 所有查询的分类 logits(包括 no-object)。
- **pred_boxes**(形状为 `(batch_size, num_queries, 4)` 的 `torch.Tensor`)-- 所有查询的归一化框坐标,表示为 (center_x, center_y, width, height)。这些值在 [0, 1] 范围内归一化,相对于批次中每张图片的单独尺寸(忽略可能的填充)。您可以使用 `~DeformableDetrProcessor.post_process_object_detection` 来获取未归一化的边界框。
- **auxiliary_outputs** (`list[Dict]`, *可选*) -- 可选,仅在启用辅助损失(即 `config.auxiliary_loss` 设置为 `True`)且提供了标签时返回。它是一个字典列表,包含每个解码器层的上述两个键(`logits` 和 `pred_boxes`)。
- **last_hidden_state**(形状为 `(batch_size, num_queries, hidden_size)` 的 `torch.Tensor`,*可选*)-- 模型解码器最后一层输出的隐藏状态序列。
- **decoder_hidden_states** (`tuple[torch.Tensor]`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每个层输出的一个张量),形状为 `(batch_size, sequence_length, hidden_size)`。
解码器在每一层输出处的隐藏状态,以及初始嵌入输出。
- **decoder_attentions** (`tuple[torch.Tensor]`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
解码器在注意力 softmax 之后的注意力权重,用于在自注意力头中计算加权平均值。
- **cross_attentions** (`tuple[torch.Tensor]`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回) -- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
解码器交叉注意力层在注意力 softmax 之后的注意力权重,用于在交叉注意力头中计算加权平均值。
- **encoder_last_hidden_state**(形状为 `(batch_size, sequence_length, hidden_size)` 的 `torch.Tensor`,*可选*)-- 模型编码器最后一层输出的隐藏状态序列。
- **encoder_hidden_states** (`tuple[torch.Tensor]`,*可选*,在传入 `output_hidden_states=True` 或 `config.output_hidden_states=True` 时返回) -- 一个 `torch.Tensor` 元组(如果模型具有嵌入层,则包含嵌入层输出的一个张量,以及每一层输出的一个张量),形状为 `(batch_size, sequence_length, hidden_size)`。
编码器在每一层输出处的隐藏状态,以及初始嵌入输出。
- **encoder_attentions**(`tuple[torch.Tensor]`,*可选*,当传入 `output_attentions=True` 或 `config.output_attentions=True` 时返回)-- 一个 `torch.Tensor` 元组(每层一个),形状为 `(batch_size, num_heads, sequence_length, sequence_length)`。
编码器在注意力 softmax 之后的注意力权重,用于在自注意力头中计算加权平均值。
- **init_reference_points**(形状为 `(batch_size, num_queries, 4)` 的 `torch.Tensor`)-- 通过 Transformer 解码器发送的初始参考点。
- **intermediate_hidden_states**(形状为 `(batch_size, config.decoder_layers, num_queries, hidden_size)` 的 `torch.Tensor`)-- 堆叠的中间隐藏状态(解码器每一层的输出)。
- **intermediate_reference_points**(形状为 `(batch_size, config.decoder_layers, num_queries, 4)` 的 `torch.Tensor`)-- 堆叠的中间参考点(解码器每一层的参考点)。
- **enc_outputs_class** (`torch.Tensor`,形状为 `(batch_size, sequence_length, config.num_labels)`,*可选*,当 `config.with_box_refine=True` 且 `config.two_stage=True` 时返回) -- 预测的边界框分数,其中得分最高的 `config.two_stage_num_proposals` 个边界框在第一阶段被选为区域建议。边界框二分类(即前景和背景)的输出。
- **enc_outputs_coord_logits** (`torch.Tensor`,形状为 `(batch_size, sequence_length, 4)`,*可选*,当 `config.with_box_refine=True` 且 `config.two_stage=True` 时返回) -- 第一阶段中预测的边界框坐标的 logits。
示例:
```python
>>> from transformers import AutoImageProcessor, DeformableDetrForObjectDetection
>>> from PIL import Image
>>> from huggingface_hub.utils import httpx
>>> from io import BytesIO
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
>>> with httpx.stream("GET", url) as response:
... image = Image.open(BytesIO(response.read()))
>>> image_processor = AutoImageProcessor.from_pretrained("SenseTime/deformable-detr")
>>> model = DeformableDetrForObjectDetection.from_pretrained("SenseTime/deformable-detr")
>>> inputs = image_processor(images=image, return_tensors="pt")
>>> outputs = model(**inputs)
>>> # convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
>>> target_sizes = torch.tensor([image.size[::-1]])
>>> results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[
... 0
... ]
>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
... box = [round(i, 2) for i in box.tolist()]
... print(
... f"Detected {model.config.id2label[label.item()]} with confidence "
... f"{round(score.item(), 3)} at location {box}"
... )
Detected cat with confidence 0.8 at location [16.5, 52.84, 318.25, 470.78]
Detected cat with confidence 0.789 at location [342.19, 24.3, 640.02, 372.25]
Detected remote with confidence 0.633 at location [40.79, 72.78, 176.76, 117.25]
```